Small dev tickets piling up: hand them to a coding agent, review the pull request
May 31, 2026
Yes, you can hand the small dev tasks you keep putting off to a coding agent. It works in an isolated environment, runs the tests and gives you back a pull request that you review before merging. It works for repetitive tasks that tests can verify, not for architecture decisions.
Here is the made-up example I keep from start to finish: a freelance developer maintains the websites of eight clients, or a small web agency maintains its clients' sites. Each has a list of small tasks: a dependency to update, a README that no longer tells the truth, an obsolete test, a missing log. Each task takes about twenty minutes (an order of magnitude, not a measurement). None is urgent, none is billed, and they always come after the mission in progress. After a quarter, that backlog slows down the real missions and nobody can say when it built up.
At a glance
- For whom
- Freelance developers and small web agencies with more small tickets than time
- You need
- A GitHub repository with a green CI, and Codex cloud or Open SWE
- Time
- A few hours for a first try (my estimate)
- Cost
- Codex cloud: see the ChatGPT plans on the official page. Open SWE: you deploy it yourself, with the cost of the model and the sandbox
- Level
- Intermediate
- Updated on
- November 1, 2026
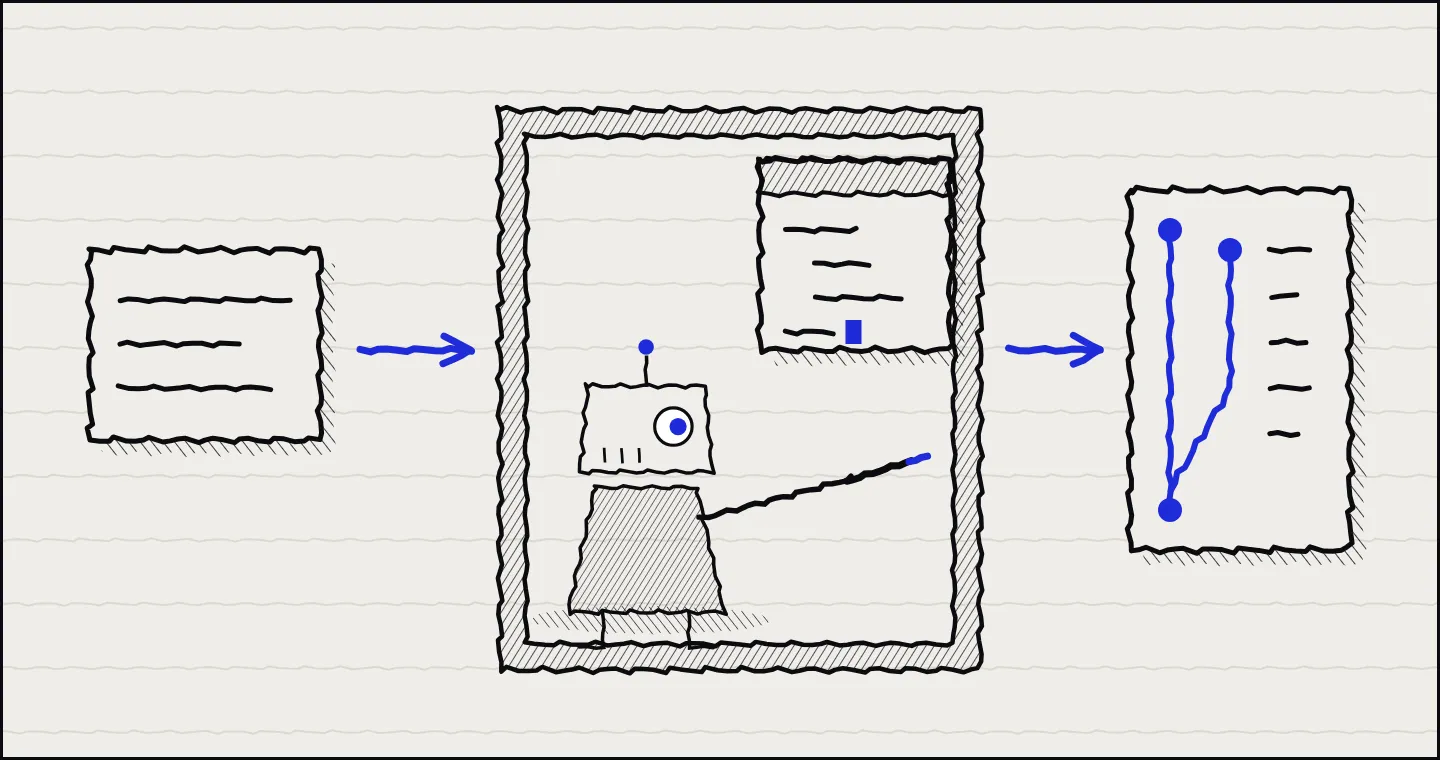
The principle: you describe the task, the agent reads the code, writes the change, runs the tests and opens a pull request. You approve it or fix it. This tutorial covers which tasks to delegate, the instruction, the guardrails and a first try this week.
Understand What a Background Coding Agent Is
A background coding agent is not an assistant that completes your code as you type. It takes an instruction, goes off to work alone in an isolated environment, and comes back with a result in the form of a pull request.
Two products illustrate the category.
OpenAI's Codex cloud. You describe a task from ChatGPT (web, mobile or desktop app), inside a cloud environment that holds your repositories and tools. Each task has its own workspace and can keep running while your computer is asleep. You review the changes and the test results, then commit or open a pull request when you are ready.
LangChain's Open SWE. It is an open-source agent that investigates a repository, implements changes in an isolated sandbox, validates them and delivers a pull request. You drive it from a dashboard, from GitHub issues and conversations, or from Slack, and it can also review pull requests. Its README warns that it is under active development, with breaking changes and no stability guarantee. To deploy it yourself, it needs a managed agent runtime: count on a project rather than an afternoon's try.
What they share: asynchronous, isolated work that ends in a pull request. You do not watch the agent work. You hand it a goal, you do something else, you review its work at the end. It is the model of a junior you give a well-scoped task to: you do not hold their hand, you review their PR.
Pick the Right Tasks to Delegate
Delegate what is repetitive, well-scoped and verifiable by tests. Keep for yourself what needs business judgment, a product trade-off or context the agent does not have.
| Level | Example tasks | Risk | Condition |
|---|---|---|---|
| 1 | Documentation from the code, logs, formatting on targeted files, a consistent rename across the repo | None | None |
| 2 | Minor dependency bumps, migrating a deprecated pattern, missing test cases on an existing function | Low | A solid test suite |
| 3 | A small, well-specified feature, a reproducible bug with a failing test | Moderate | Human review is non-negotiable |
At the made-up agency, the dependency updates across eight client sites make a good level 2 series: same gesture, tests to run, a verifiable result. Renaming a variable across fourteen files is level 1.
What you do not delegate: architecture decisions, changes that touch security or payments, any business trade-off that is not written in the code. The agent does not know why that ugly hack has existed for two years. You do.
Practical test: if you cannot write the instruction in three sentences with a way to verify the result, the task is not ready. Reword it, or keep it.
Framing the Agent: The Instruction Decides Everything
An agent is literal: it does what you write, not what you think. A vague instruction gives a vague PR, and you lose more time reviewing shaky work than doing the task yourself.
A good instruction has four elements:
- The precise goal. Not "improve the tests", but a function, a file and named cases.
- The scope. What the agent may touch, and what it leaves alone. Without a scope, an eager agent refactors three neighboring modules while it is at it.
- The success criterion. A command that says whether it is done and correct. This is what separates a clean delegation from a bet.
- The constraints. Code style, commit format, files never to modify.
A template instruction, to adapt to your task:
Goal: [what you want, with the function or file and the cases to cover, for example tests for `parse_invoice` in `billing/parser.py`: valid invoice, negative amount, missing currency].
Scope: [the files the agent may modify, for example only `tests/billing/`]. Do not touch any other file.
Success criterion: [the command that must pass, for example `pytest tests/billing/`] and [the threshold to reach, if you have one].
Constraints: [code style, commit format, files never to modify].
The riskier the task, the tighter the instruction. For a doc update, two sentences are enough. For a pattern migration, write it like a ticket for a junior dev you cannot interrupt while they work.
The Guardrails: Human Review and Isolated Environment
An agent without guardrails is an intern with prod access and nobody to review the work.
Guardrail one: isolation, and its limits. Both products run the agent in an environment separate from your machine, so a destructive command does not touch your workstation. Never bypass that by running an agent directly on your workstation with full access. But isolation protects your machine, not your repositories: the Open SWE README states that its sandboxes may have network access and normally receive GitHub access across the whole app installation. Limit the repositories the agent can reach, with the minimum credentials.
Guardrail two: the mandatory pull request. Turn on branch protection for your main branch in GitHub, with a required review before merge: the agent then cannot push there without going through a reviewed PR. The PR goes through your CI (tests, lint, build) like a human's, and a human reviews it. This holds even for a level 1 task. A wrong doc generated by an agent and merged without review is still a wrong doc signed by you, or by your agency.
Guardrail three: the permission scope. For Codex, the cloud environment settings let you limit internet access. Cut whatever is not needed: an agent that does not need the internet for its task should not have it. Expose only the secrets that are strictly necessary to the sandbox.
Concrete Setup: Your First Agent This Week
Here is how to launch a real delegation on a real task.
Step 1: pick a level 1 task. Take the most harmless one on your list, for example a README that no longer reflects the project structure. You want the first try to succeed so you build confidence, not to prove the agent can do everything.
Step 2: prepare the repo. Check that your tests run and pass locally. An agent works well on a repo with a green CI and tests that mean something. If your suite is red or nonexistent, start there: the agent needs it to know whether it succeeded.
Step 3: connect the agent to GitHub. For Codex cloud, you create an environment with your GitHub repositories from ChatGPT, publish it, then start a task. For Open SWE, follow the installation guide in the repository. Start on a non-critical repo, an internal project or a test repo, while you calibrate.
Step 4: write the instruction with the four elements from section 3. Reread it as if you were handing it to someone you cannot reach during execution.
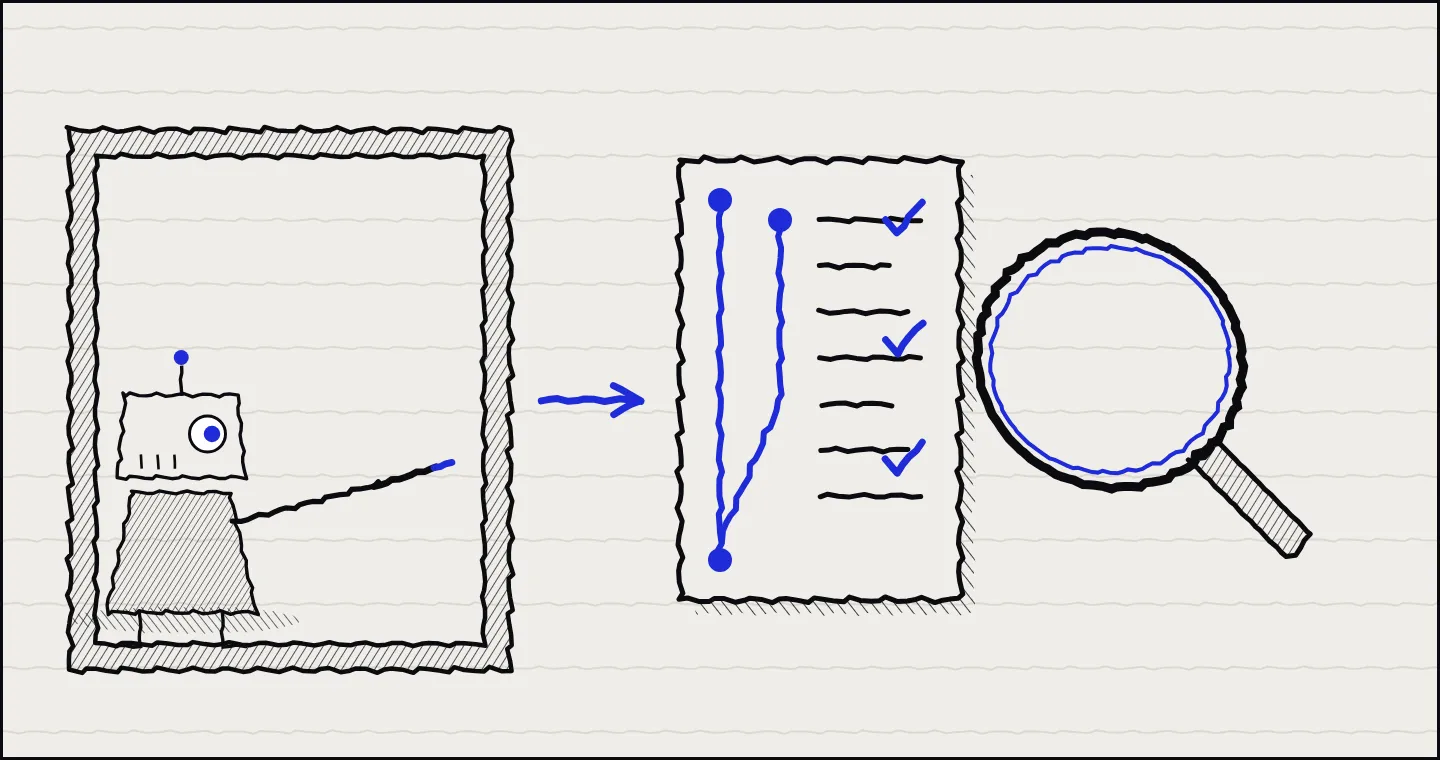
Step 5: launch, then watch the start. If your tool shows a plan before running, read it: it is your best moment to correct course. Otherwise, wait for the PR.
Step 6: review the PR like a human's. Green CI tests, the full diff read, scope respected. If all is good, you merge. If not, you send feedback to the agent or take over by hand. Codex also accepts @codex review in a PR comment for a first automatic review: it does not replace yours.
Step 7: note what worked. Keep the instructions that produced a good PR as templates, and note what went wrong. When a category of tasks runs well, you can hand over the whole series: that is where the gain becomes regular.
The most common setup mistake: starting with a complex task to "really test" the agent. You then test two unknowns at once, the difficulty of the task and the reliability of the tool. A trivial first try, a slightly harder second one, and your confidence rests on results.
Final checklist
0 of 6
And Now?
A coding agent replaces neither your judgment nor your team's. It takes away the repetitive chores that eat time, so you keep it for architecture, trade-offs and the client relationship. The agent does the thankless work, you review, approve and stay responsible for what ships.
So the right question is not whether coding agents work. Codex cloud and Open SWE exist and open verifiable pull requests. It is where to start with your stack, your CI and your security constraints, without delegating the wrong task at the wrong time. To estimate what it costs you in model usage, see how to control Claude token costs. To keep a cool head about the real gain, read the AI productivity paradox.
The next step is a small tool for your business in one afternoon: same principle, and how far you can go without trapping yourself. I share this kind of how-to in my newsletter, you can sign up right below.