
Cost vs Performance Across AI Models, With Gemini as the Example
May 31, 2026
To find out whether a task can move to a cheaper model, you measure: you replay 50 to 100 real cases on both models with the same prompt, and you compare the rate of correct answers with the cost. On the Gemini lineup, the price gap runs from 2.7 to 25 times depending on the lightweight model you pick (prices of November 1, 2026).
A made-up example that I keep throughout: a freelancer wired an automatic support-email sorter into a client's online shop. The sorter runs on the flagship model picked on launch day, nobody went back to it, and the client's API bill never goes down. They pay the premium rate to decide whether an email is about an invoice or not, a task that does not need the best model on the market.
At a glance
- For whom
- Freelancers and small agencies who plugged an AI model into a product and want a lighter bill without losing quality
- You need
- The list of your AI tasks and 50 to 100 real cases where you know the right answer
- Time
- Half a day per task (my estimate)
- Cost
- Depends on your usage (a few API calls for the tests)
- Level
- Intermediate
- Updated on
- November 1, 2026
Two instincts cost money. The naive one: move everything to the cheapest model. The lazy one: leave everything on the biggest model "to be safe". This tutorial gives you the method to decide task by task, with criteria and a test protocol, without guessing.
Understand what you're actually paying for
Before you arbitrate, you need an honest order of magnitude. Prices move fast, but the structure holds: a model bills per million tokens, separately for input (what you send) and output (what it generates, thinking included), and output costs more than input.
I take the Gemini lineup because it shows the gap well. Here are the prices per million tokens, standard paid tier, from the official Google pricing page (page read on November 1, 2026):
| Model | Input | Output |
|---|---|---|
| Gemini 4 Argon | $2 | $10 |
| Gemini 3.8 Flash | $0.75 | $3.75 |
| Gemini 3.5 Flash-Lite | $0.30 | $2.50 |
| Gemini 2.5 Flash-Lite (text) | $0.10 | $0.40 |
The ratios come straight from the table. Between Gemini 4 Argon and Gemini 3.8 Flash, input and output both cost 2.7 times less. Against Gemini 3.5 Flash-Lite, it is 6.7 times less on input and 4 times less on output. Against Gemini 2.5 Flash-Lite, it is 20 times less on input and 25 times less on output.
Run the math on the freelancer's task. Classifying a support email is about 500 input tokens and 10 output tokens (sample values). At 300 emails a day over 30 days, that is 4.5 million input tokens and 90,000 output tokens a month:
- On Gemini 4 Argon: $9.90 a month.
- On Gemini 3.8 Flash: about $3.71.
- On Gemini 3.5 Flash-Lite: about $1.58.
- On Gemini 2.5 Flash-Lite: about $0.49.
Between the first and the last, a factor of about 20 for the same task, and about 40 once Argon's price moves to $4 / $20. At this volume, the saving stays around $9 a month: for this task, the switch depends as much on quality as on the bill. With 100 times more emails (30,000 a day), the same calculation gives about $940 a month. A classifier does not need to reason, it needs to stick the right label on, provided quality holds: the next steps show how to check it.
Look at the output price too. On generative tasks (writing, summarizing, customer replies), output is the bulk of the bill. On these four models, it costs 4 to 8.3 times input.
Map your AI tasks before you touch the model
You can't arbitrate what you haven't listed. The first step isn't technical at all: it's an inventory. Open a spreadsheet and list every place an AI model runs in your business, or in your client's. For each one, note three things.
First, volume: how many times a day the task runs. A task that fires 5 times a month doesn't deserve an hour of optimization. One that fires 10,000 times a day deserves a close look.
Second, the nature of the task. File each use into a family, because the family decides almost everything:
- Extraction and classification: pull out a structured field, stick a label on, answer yes or no. Little creativity, verifiable output.
- Transformation: rephrase, translate, summarize, reformat. The meaning is given, the model rearranges it.
- Simple generation: write a short email, a product description, a templated reply. Creation, but framed by a tight brief.
- Reasoning: analyze a situation, weigh options, write non-trivial code, follow a long logical chain. This is where the big model most often wins.
Third, error tolerance. A mistake on an internal sort is fixed in 10 seconds. A mistake on a quote sent to a client costs you reputation. A high-volume, low-tolerance task needs more care than a high-volume, high-tolerance one.
With those three columns, candidates start to surface. High-volume extraction and transformation tasks can often move to a lightweight model. High-stakes reasoning tasks stay on the big model. The real arbitration work happens between the two.
Switch criteria: when to drop down a tier
Once your tasks are mapped, four signals say "this one, you can move it."
The task has a verifiable answer. If you can objectively say whether the output is right or wrong (the correct label, the correct extracted date, valid JSON), a lightweight model has a good chance of doing the job. The big model earns its keep when the "right answer" requires judgment.
The output is short and constrained. Picking from a closed list, filling a schema, answering yes or no. The more bounded the output, the less raw reasoning power matters, and the more the quality gap tends to disappear.
The context is limited. If the task fits in a few thousand tokens and doesn't require holding a 100-page file in mind, a lightweight model is more likely to keep up. Very long contexts and long reasoning chains are where big models most often keep the edge: check it with your test set.
The volume justifies the effort. Migrating a task costs testing and recalibration time. Below a certain volume, the savings don't pay for the effort. Above it, every day left on the old model costs money for nothing.
Conversely, keep on the big model multi-step reasoning, analysis of ambiguous cases, complex code, and any deliverable that goes straight to a client without review. The extra cost is small there because volume is low, and an error is expensive.
A note on versions: a newer model isn't always cheaper. On the Google page, Gemini 3.5 Flash-Lite costs $0.30 / $2.50, against $0.10 / $0.40 for Gemini 2.5 Flash-Lite: 3 times more on input and 6.25 times more on output. The "newer therefore adopt it" logic is wrong when you optimize cost. You move up to the recent model to gain quality or speed, and down to an older or lighter model to pay less. These are two opposite decisions, don't confuse them.
How to test a switch without risk
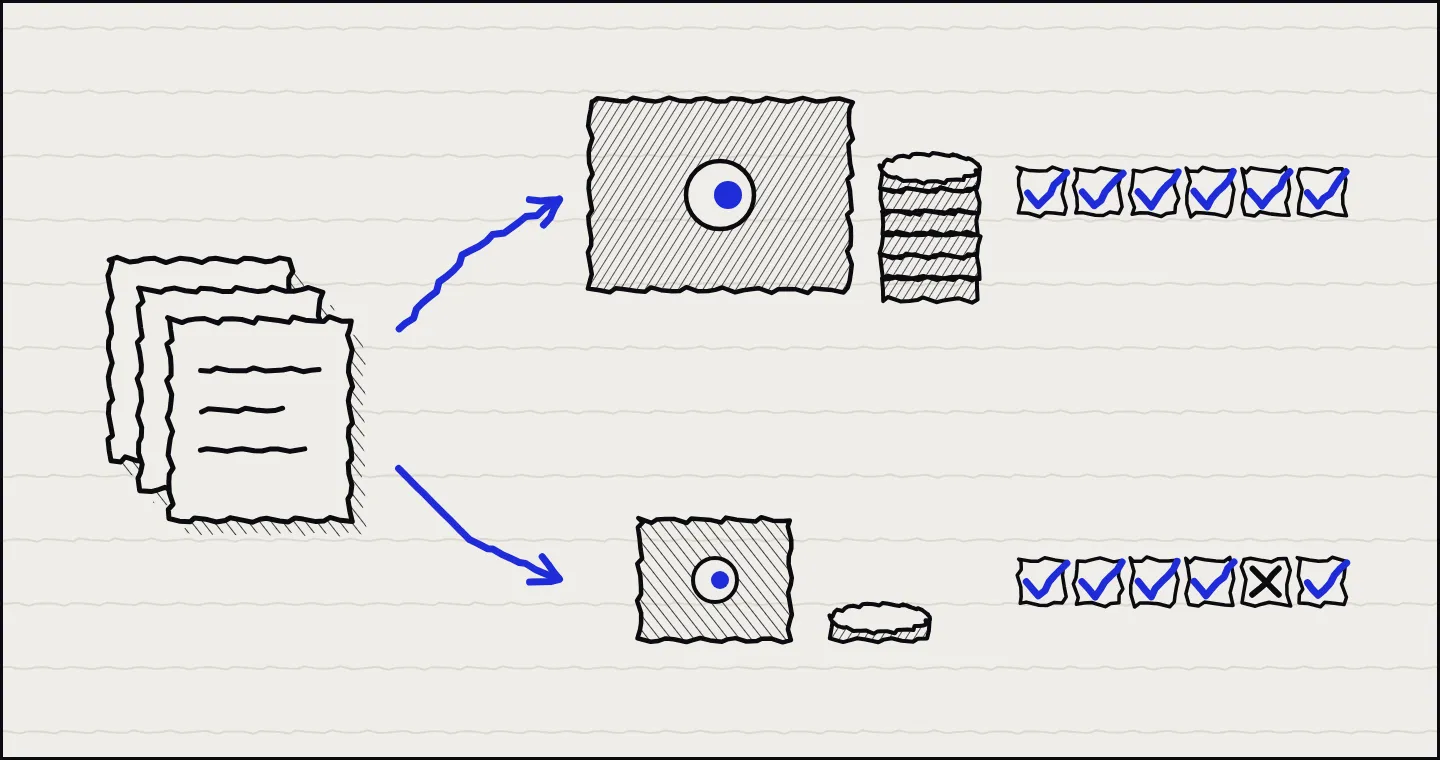
A switch isn't decided by reading a public benchmark. A benchmark tells you how a model behaves on generic tasks. You need to know how it behaves on your task, with your data. Here's the protocol, in four steps.
Build a representative test set. Take 50 to 100 real cases that have run through your task, with the correct answer known. For classification, that's inputs already labeled correctly. For extraction, documents whose expected content you already know. If the data comes from a client, anonymize it. This set is your ground truth, it doesn't change between tests.
Run both models on the same set. The current model and the lighter candidate, with exactly the same prompt and the same inputs. You get two columns of outputs to compare.
Measure the gap on your metric, not on a vibe. For a verifiable task, count each model's rate of correct answers. If the big model hits 94 percent and the lightweight one hits 91 percent (sample figures), the question becomes simple: are 3 points of accuracy worth the price gap, given your error tolerance on this specific task? Sometimes the answer is no, and you switch. Sometimes it is yes, and you keep the big model knowing why.
Recalibrate the prompt before concluding. A lightweight model that fails with the big model's prompt sometimes succeeds with one cut for its size: two or three examples added, a stricter output format. Before you declare a model "not good enough," give it the prompt it deserves. Many failed switches are prompts nobody took the time to adapt.
Count half a day per task (my estimate). The decision this test informs replays on every request, so the time pays back faster the higher the volume.
The decision table
Once your tasks are measured, boil it all down to a simple grid. It is a starting point to adapt to your context and your measurements.
| Task type | Volume | Error tolerance | Recommended model | Why |
|---|---|---|---|---|
| Classification, extraction | High | Medium to high | Flash-Lite | Verifiable answer, short output, the quality gap tends to disappear |
| Transformation (summary, translation, format) | High | Medium | Standard Flash | Meaning is given, model rearranges, good value |
| Short framed generation (templated email, product copy) | Medium to high | Medium | Standard Flash | Creation bounded by the brief, light review |
| High-stakes generation (quotes, replies to an executive) | Low | Low | Big model | Low volume so limited extra cost, errors costly |
| Reasoning, analysis, non-trivial code | Low to medium | Low | Big model | Reasoning is what justifies the premium rate |
| Long context (100-page file) | Variable | Variable | Big model | To confirm with your test set |
The logic fits in one sentence: the more verifiable, short and tolerant the task, the further down a tier you can go. The more it demands judgment, long context, or zero error, the more the big model justifies itself. Volume acts as a multiplier: it turns a small per-request saving into a large monthly number, so it decides where to invest your arbitration time.
Architect so you can change your mind
The best decision you make today will be stale in a few months: models change and prices move, as the Google page shows with prices that change on set dates. The real protection isn't picking the right model once, it's being able to swap it without rewriting your system.
Never hard-code the model name in the middle of your business logic. Pull it out into a config, per task type:
MODELS = {
    "classification": "gemini-2.5-flash-lite",  # example: replace with the model that passes your test set
    "generation": "gemini-3.8-flash",
    "reasoning": "gemini-4-argon",
}
The day a new model ships cheaper and just as good, you change one line and re-run your test set. The day a provider raises prices, you compare in an afternoon instead of a week.
This discipline makes arbitration continuous instead of one-off. Once your test set exists and your model is parameterized, re-evaluating a switch takes half a day, not a project. You can redo it on every model release that matters to you and keep the best value.
Final checklist
0 of 6
What now?
Arbitrating cost and performance across models is a management decision that hits your margin, or your client's, and it replays on every request the model handles. If you haven't listed what you automate yet, start from the 12 AI automations and where to begin, then come back and pick the right model for each one. The cost of an AI project doesn't stop at the API line either: the three hidden costs of an AI project complete the picture.
The next step is to do the same exercise on the Claude side: mastering Claude token costs, with the effort level, the cache and batches. I share this kind of method in my newsletter, you can sign up right below.


