
Mastering Claude Token Costs: Tune Thinking to Control Your API Bill
May 31, 2026
To cut a Claude bill without hurting quality, you adjust six things: you measure every call, you lower the effort level, you send each task to the right model, you cache repeated instructions, you move non-urgent work to batches, and you trim the context. Every price quoted is linked to the official page, with the date it was read.
A made-up example that I keep throughout: a three-person agency delivers a support-email assistant to a client, wired to the Claude API. The first month, the bill lands well above the planned budget. Nobody knows which function consumes what, and the assistant calls the same model on every email, even to rephrase a single line.
At a glance
- For whom
- Freelancers and small agencies who plugged the Claude API into their product or a client's
- You need
- An Anthropic API account and access to the code that calls Claude
- Time
- An hour or two to measure and set the effort level, half a day for routing (my estimate)
- Cost
- No tool to pay for on top of the API
- Level
- Intermediate
- Updated on
- November 1, 2026
The most misunderstood lever is the thinking level: how much Claude "thinks" before it answers. That thinking is billed, and you can set it. The six levers are numbered 1 to 6: in practice, you start with lever 6, measurement, then move to levers 1 and 2. Each comes with the problem, the steps and a calculation you can redo on your own workload.
Tune the thinking level: lever number one
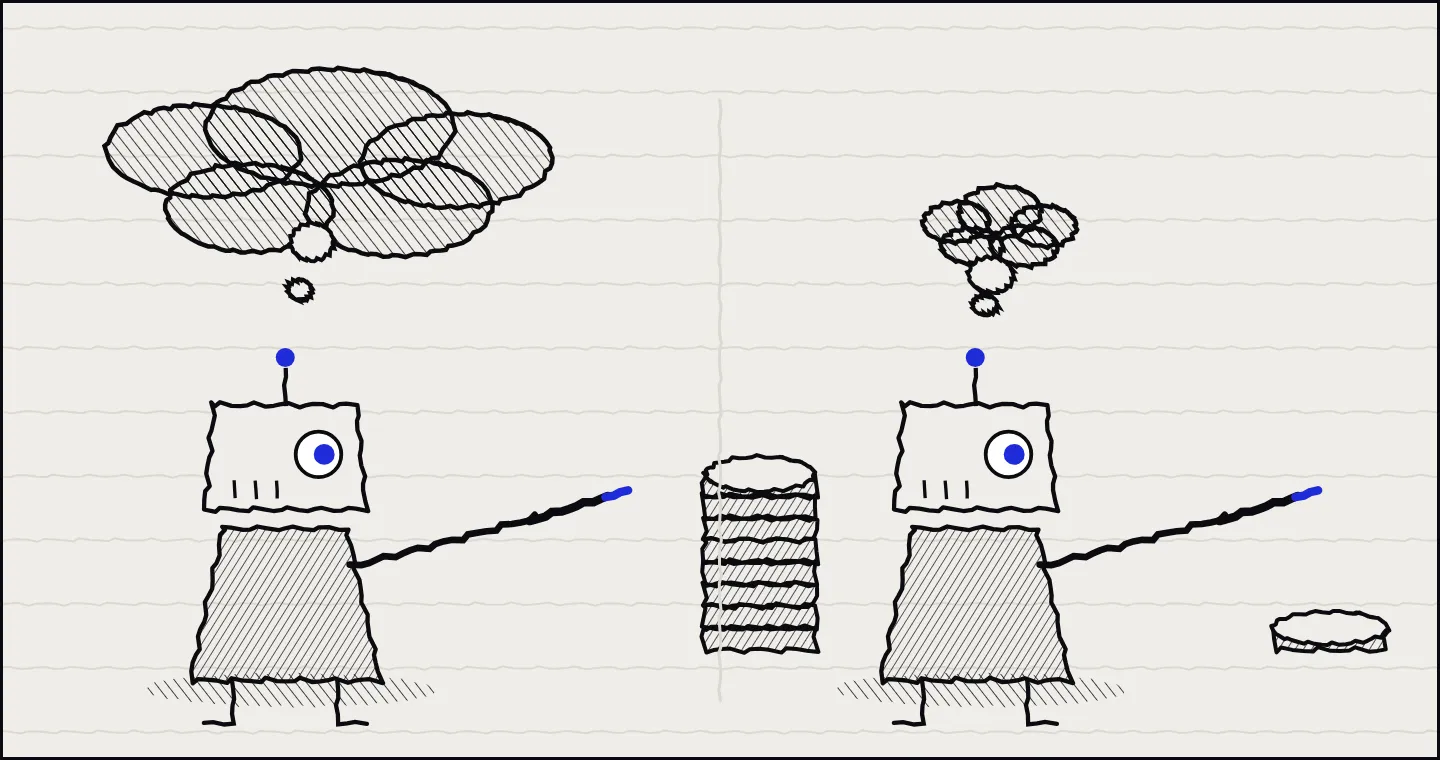
The trap is letting the model think at full depth everywhere, "just in case". Claude decides on its own, request by request, whether to think and how much (this is adaptive thinking). Every thinking token is billed as output. A model that thinks 8,000 tokens to rephrase a sentence costs you 8,000 output tokens for nothing.
What you set is the effort level, with five values: low, medium, high, xhigh and max. The lower the level, the less Claude thinks, and the cheaper the call. According to the effort page, the default level is high on most models, including Sonnet 5.5, and medium on Opus 5.5 and Haiku 5.5. If you set nothing on Sonnet 5.5, you pay for high. The parameter goes in output_config, not in the thinking object:
import anthropic

client = anthropic.Anthropic()  # the key is read from the ANTHROPIC_API_KEY environment variable

response = client.messages.create(
    model="claude-sonnet-5-5",
    max_tokens=16000,  # thinking counts toward max_tokens: leave room
    thinking={"type": "adaptive"},
    output_config={"effort": "medium"},  # low, medium, high, xhigh or max: lower = thinks less = cheaper
    messages=[{"role": "user", "content": "[your request]"}],
)
print(response.usage)
Effort is guidance for the model, not a token budget: at a low level Claude still thinks on a truly hard problem, just less. For chat or any latency-sensitive use, the docs recommend starting at medium or low on Sonnet 5.5. You go up for complex requests, and you check on your own cases that quality holds.
Since Claude 4.7, models reject the old fixed-budget setting (thinking.type: "enabled" with budget_tokens) and return a 400 error, according to the extended thinking page. That page marks it as deprecated. It still works on older models such as Sonnet 4.6 or Haiku 4.5, where you set the ceiling yourself:
response = client.messages.create(
    model="claude-sonnet-4-6",
    max_tokens=8000,
    thinking={"type": "enabled", "budget_tokens": 4000},
    messages=[{"role": "user", "content": "[your request]"}],
)
Anthropic's advice for this setting: for a simple task, start near the 1,024-token minimum; for a complex task, start at 16,000 or more, then adjust to your latency and quality needs. Above 32,000 tokens, the docs recommend batch processing: long requests risk timeouts.
In the agency example, the assistant runs on Sonnet 5.5 with no setting, so at high. Short support emails are the first place to test medium, then low.
Pick the right model for each task
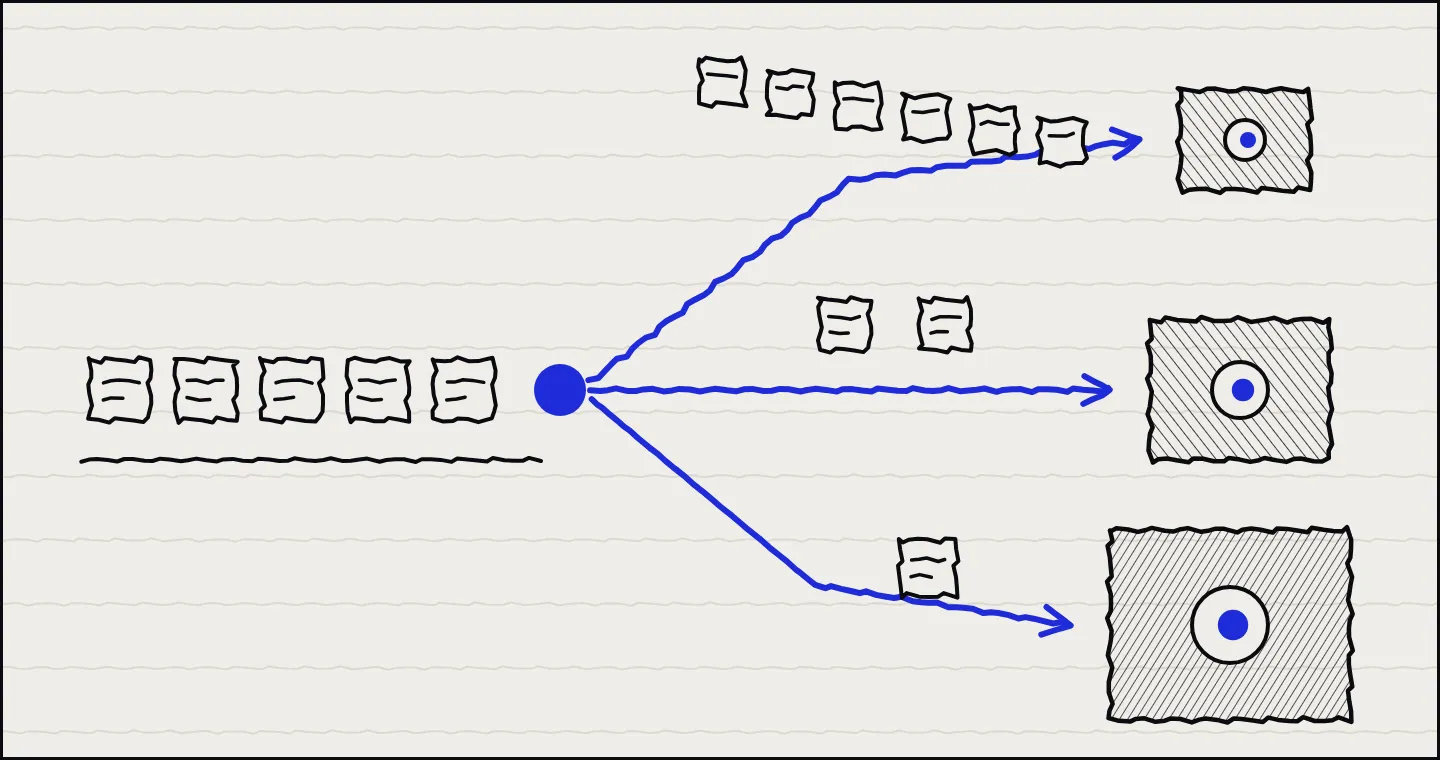
The most expensive mistake: running everything on the most powerful model. Opus is excellent at hard reasoning, but paying for it to classify a support ticket or pull a date out of a PDF means paying the premium rate for work that lighter models can do.
Here are the rates per million tokens, read on November 1, 2026 from the official pricing page:
| Model | Input | Output | Cache read |
|---|---|---|---|
| Claude Haiku 5.5 | $0.10 | $0.50 | $0.01 |
| Claude Sonnet 5.5 | $2 | $10 | $0.10 |
| Claude Opus 5.5 | $4 | $20 | $0.20 |
For Haiku 5.5, these prices apply to prompts up to 100,000 tokens. Beyond that, the page lists $0.50 for input and $2.50 for output. The previous generation is still listed and costs more than its replacement: Opus 4.8 at $5 / $25, Sonnet 4.6 at $3 / $15, Haiku 4.5 at $1 / $5. The page also states that models from Claude 4.7 onward produce about 30% more tokens for the same text: compare the cost of real calls, not just the price per million.
The ratios come straight from the table. From Opus 5.5 to Sonnet 5.5, input and output both cost 2 times less. From Opus 5.5 to Haiku 5.5, they cost 40 times less. If 70% of your requests leave Opus 5.5 for Sonnet 5.5 and all have the same size, your bill drops by 35%. To Haiku 5.5, it drops by about 68%. This is a calculation on the price grid, not a measurement of your workload: the default effort level differs (high on Sonnet 5.5, medium on Opus 5.5), so output tokens will not be identical from one model to the other. Measure on real calls.
To split your calls, segment by real complexity:
- Haiku for simple volume. The docs present it for classification, extraction and routing.
- Sonnet for the bulk of production: writing, summarizing, customer support.
- Opus for hard reasoning, when a mistake is costly.
In practice you put a small router upstream: a first simple rule (length, task type, keyword) that sends each request to the right model. You can also use Haiku as the routing classifier: at $0.10 per million input tokens, classifying a 500-token request costs $0.00005.
Turn on prompt caching
If you resend the same large block on every call (system instructions, product docs, examples, conversation history), you make it reprocess in full and pay full price each time. That is money spent on identical content.
You mark the stable part of your prompt as cacheable. The API keeps it and rereads it later at a reduced price. The multipliers from the pricing page:
- Cache write (5 minutes): 1.25 times the base input price.
- Cache write (1 hour): 2 times the input price.
- Cache read: 0.1 times the input price, and 0.05 times on Opus 5.5 and Sonnet 5.5.
The page states that the 5-minute cache pays for itself from the first reread, the 1-hour cache from the second. A sample calculation on Sonnet 5.5: 20,000 tokens of instructions cost $0.04 per call without cache, and $0.002 as a cache read. Over 1,000 calls, that is $40 versus $2 for this part, writes aside. The bigger your fixed context is compared with the variable question, the more the gap matters.
Switch to batch processing (Batch API)
Plenty of tasks do not need a live answer: generating 500 product descriptions, analyzing a month of customer comments, classifying a ticket export. They still get sent to the synchronous API at full price, out of habit.
You group these requests and send them through the Batch API. The pricing page lists a 50% discount on input and output. According to the batch processing page, most batches finish within an hour, and a batch expires if it is not processed within 24 hours. The pricing page also says the cache multipliers stack with the batch discount.
All your non-urgent volume goes to half price, with a delay as the only cost. It is the right place for regular background analyses.
Control the context and the output ceiling
Two silent leaks inflate a bill without anyone noticing.
The first: people stack whole documents, full histories and raw tool outputs into the context, most of which does nothing for the answer. Every token sent is billed as input, on every call.
The second: max_tokens is a ceiling, not a length instruction. It cuts the answer when it reaches it, it does not make the answer shorter. With thinking, that ceiling covers thinking and text together, so setting it too low cuts you off mid-answer.
What you do:
- Trim the context: send only what serves the request. Retrieve the right passages (search, history summary) instead of sending everything.
- Ask for the length you want in the prompt ("answer in 3 bullets", "strict JSON, no commentary"), and keep
max_tokensas a safeguard. - Recalibrate your estimates when you change model generation: the new tokenizer produces about 30% more tokens for the same text, according to the pricing page.
It is the least glamorous lever. To find out which of these five levers matters in your case, move on to measurement.
Measure before you optimize
You cannot pilot what you do not measure. If you only look at the monthly bill, you discover an overrun a month too late. Yet the usage field returned on every call gives you everything in real time: input tokens, output tokens, cache writes and cache reads.
import json

def log_usage(function, model, usage):
    # the cache fields can be None depending on the response
    print(json.dumps({
        "function": function,
        "model": model,
        "input": usage.input_tokens,
        "output": usage.output_tokens,
        "cache_write": usage.cache_creation_input_tokens,
        "cache_read": usage.cache_read_input_tokens,
    }))

# after each call: log_usage("support-email", "claude-sonnet-5-5", response.usage)
- Log the
usageof every call with a label (which function, which model, which task type). - Aggregate by day and by function in a simple table.
- Spot the three cost sources that weigh the most, and apply levers 1 to 5 in that order.
In the agency example, this table shows which function of the assistant burns the budget before you touch anything. You move from a bill you endure to a bill you pilot: you see a drift within hours, and you pick a model on numbers.
Final checklist
0 of 7
And now?
An API bill does not run away because of a single setting: the model, the effort level, the cache and the context together decide what you pay. The most useful move is still to know where the money goes before you touch anything.
The next step is weighing cost against performance across AI models, with Gemini as the example: the same question, task by task, with a test set to decide. If you run background agents, their consumption is measured the same way, and the tutorial on coding agents shows what you can hand them. For the full bill of an AI project, there is also the three hidden costs of an AI project. I share this kind of how-to in my newsletter, you can sign up right below.


