The Real AI Blocker Isn't the Model, It's Access to Your Data
By Anis Hammouche·June 22, 2026
The real blocker in an AI project is not the model, it is access to your data. If your clients sit in a booking tool, your payments in another app and your tracking in a spreadsheet kept by hand, no model will answer you correctly, not even the best one of the moment.
Take Malik, a freelance fitness coach (an invented character, like the figures below). He sees a demo: someone connects a model to three documents, asks a question and gets a clean answer. He concludes the matter is settled and wants an assistant that answers his clients: "When is my next session? Where am I in my program?" Six weeks later the project has stalled, and nobody can really say why. The technology worked, after all. In the demo.
This scenario is common: people think the job is to pick the right model. In reality the model has become the easy part. The real work, the part the demo hides, is access to the data.
Why the model is no longer the problem
Today's general-purpose models can summarize, classify, extract, reword and answer at a level that is more than enough for most needs of a freelancer or a small agency. The gap between two serious providers shows up less on your real cases than in technical rankings, which look nothing like your daily work.
The direct consequence: when an AI project disappoints, it is rarely because the model was not good enough. It is because it was given the wrong data, dirty data, or no reliable data at all. The model always answers something. If it answers off target, first look at what you gave it to read.
Where projects really stall
The demo succeeds because it cheats, without bad intent. You pick three clean, recent, well-written documents and ask a question whose answer you already know. Real life reveals what the demo avoided. With Malik, four things jam.
The data lives in three tools. Sessions are in the booking tool, payments in an invoicing app, load and measurement tracking in a spreadsheet. None of them talks to the others. The model does not know where to look, because nobody told it where the truth is.
Export is impossible or partial. In this invented example, the booking tool exports the client list but not the session history. Without a clean export the data stays locked in: you cannot hand it to the model without retyping it. If you are choosing a tool today, test its export before you subscribe.
The hand-kept Excel file is a mess you no longer see. The same client appears under three spellings, "Sofia M.", "Sofia Martin" and "S. Martin". Out of 120 rows (an invented figure), about thirty are duplicates of this kind. One column mixes kilos and percentages, another has dates in words and in digits. The model does not arbitrate, it reproduces the mess you hand it.
Permissions are not set. A coach keeps information that touches clients' health, such as an injury or a weight. Data concerning health is among the sensitive data defined by the CNIL (the French data protection authority), and depending on the context an injury or a weight may fall under it: better to treat it with care. An assistant that answers Sofia with another client's history is not a time saver, it is an incident waiting to happen. I go through what is better not to paste into a consumer tool in where your data and your clients' data go.
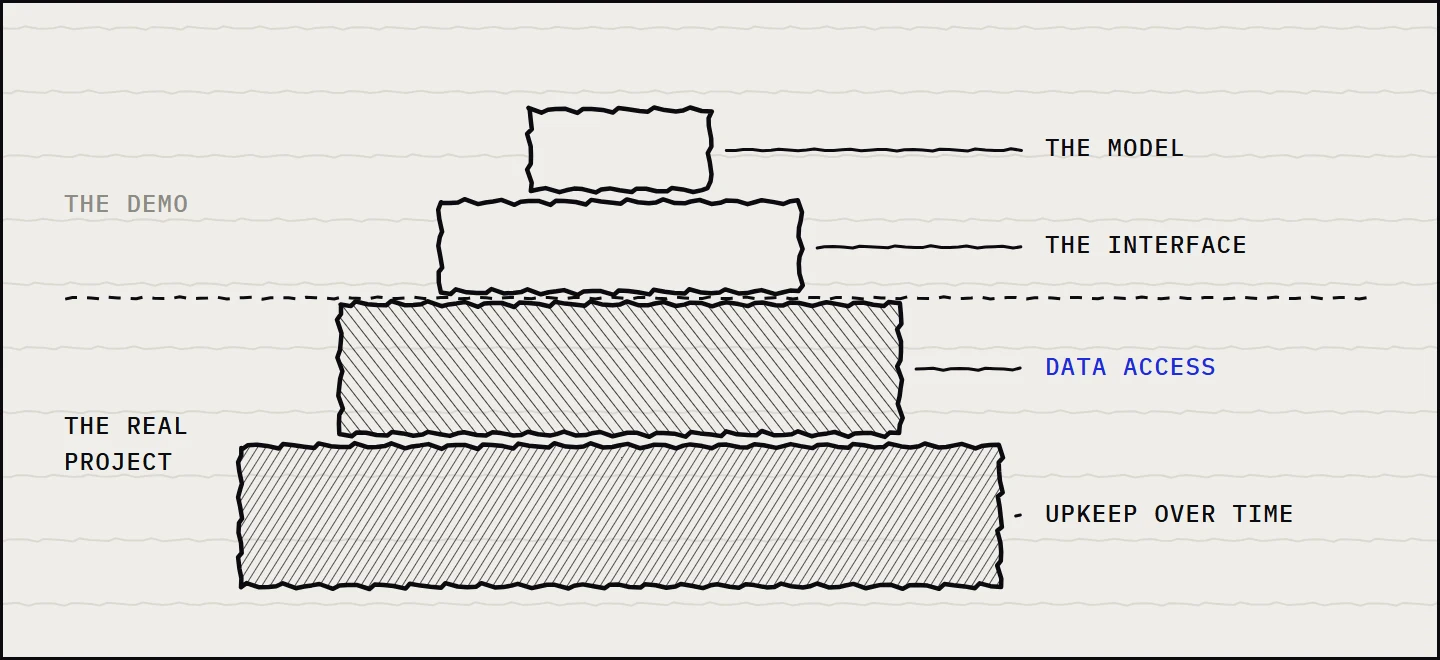
The four layers of an AI project, from the most visible to the most decisive
| Layer | What it is | Real effort for a small business | Where it breaks |
|---|---|---|---|
| The model | The engine that generates the answer | Low, it is a choice | Rarely |
| The interface | The chat or the button in the tool | Medium | Sometimes, for lack of use |
| Data access | Connecting the model to the right sources, up to date, with the right permissions | High | Almost always |
| Upkeep over time | Who keeps the data current and clean | Ongoing | After a delay |
The demo is played on the first two rows. The real project is won or lost on the last two. It is the opposite of the attention they get at the start.
How to frame data access before plugging in AI
This work can be scoped, and it does not require overhauling your tools. It requires answering a few precise questions before writing the first line of code. Fill in this card for each piece of information your assistant needs.
Information the AI needs: [e.g. a client's session history]
Where the reference version lives: [tool or file]
Export possible: [yes as CSV, yes partial, no]
State: [up to date, duplicates, mixed formats, empty fields]
Who may see it: [me only, the client concerned, my team]
Who keeps it up to date: [name and frequency]
A few rules for filling it in.
- One place is the reference for each piece of information. If two tools hold the price of a session, decide which one wins. That decision is worth more than the choice of model.
- Clean only what the use case needs. A targeted cleanup of the project's data is enough. No need to tidy your whole spreadsheet to get started.
- Set the access boundaries before connecting anything. The tool must respect who may see what.
- Name someone who keeps the data up to date. Without that, the tool degrades silently, and you find out at the first bad answer in front of a client.
The same blocker in a small agency
Studio Trame, a three-person communications agency (invented), would like an assistant that prepares each client's weekly update. Briefs are in emails, the schedule is in a notes tool, invoices are in a separate app. The oldest client exists under two names, with two different contacts. Before talking about models, the agency has to decide which tool is the reference for a client's name, and who corrects it. My estimate, with no measurement behind it: half a day's work rather than a project of several months, and it conditions everything else. The thinking is the same as for choosing a vertical tool over a generic assistant: a scoped tool is only worth something when it is wired to clean data.
Changing the model instead of scoping access: the mistake that costs the most
The classic mistake is to change the model when the project disappoints. You hop from one provider to the next hoping the next one will understand better. The result does not move, because the problem was never there.
As long as your data is scattered, contradictory and without an owner, the best model in the world will faithfully reproduce your mess. The reverse is also true: once access is scoped, even a modest model gives results you really use. The lever is not in the engine, it is in what you give it to read. When access means connecting several tools, cleaning a history and plugging in an agent, it becomes custom automation or development work, and that is one of the projects I take on.
FAQ
Do I need a big data management project before doing AI?
No. It is even the best way never to start. Scoping happens at the level of the task, not of your whole business. You prepare the data this precise task needs, nothing more, and widen later if the next task justifies it.
How do I know whether my data is ready for AI?
For each piece of information the task needs, can you name a single up-to-date, reliable place whose content you know how to export? If yes, you are ready. If not, the card above shows what is left to do before connecting the model.
So the choice of model does not matter at all?
It matters, but less than people think, and later in the process. Start with a solid general-purpose model, put the effort into data access, and only revisit the model if a precise need justifies it, for example a confidentiality or cost constraint.
How long does it take to scope this access?
It depends on the state of your tools. Filling in the card for one precise task takes an evening. Cleaning a history or getting an export that does not exist can take much longer. I do not give a standard duration without knowing the tools: start with the card, it tells you whether the job is small or big.
Once access is settled, the remaining question is whether the tool pays off for you: the ROI of an AI tool takes a few lines to work out. I tell the rest in my newsletter, right below.